Guides
How to keep a RAG knowledge base fresh without re-embedding everything
24 Oct 2026 · 8 min read
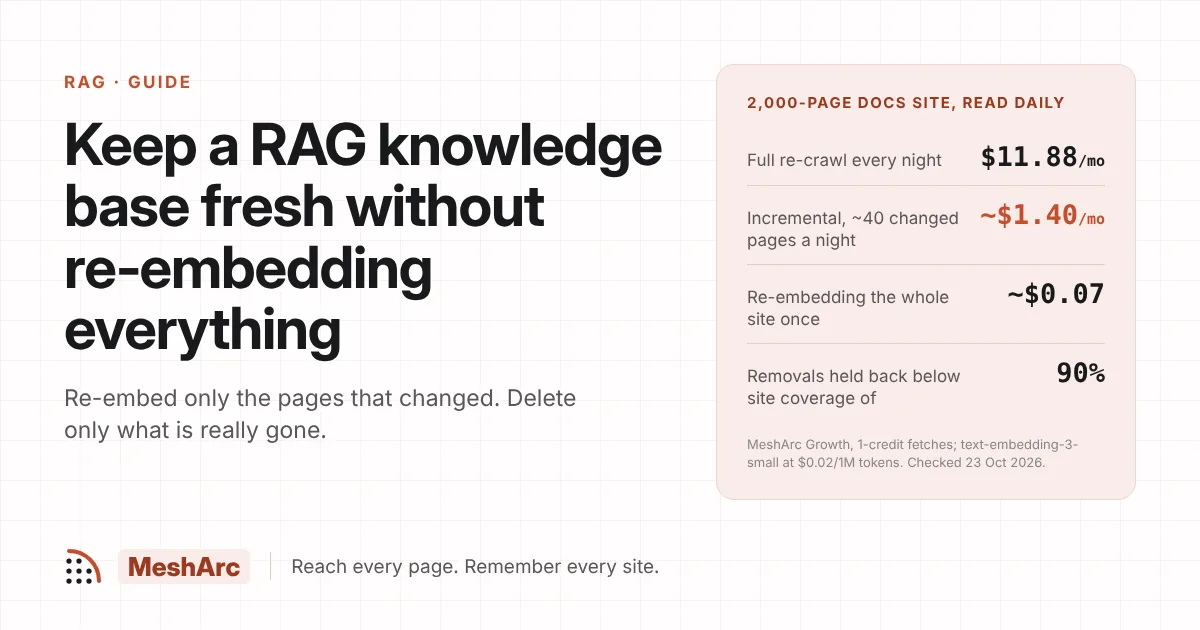
A stale embedding scores as well as a fresh one. So an assistant keeps recommending a deprecated feature and quoting a deleted page, and nobody notices until a customer does. Re-indexing everything nightly fixes it and costs a fortune in embedding calls.
Qdrant, Weaviate and pgvector, tested against live instances, plus Pinecone. Or export llms.txt and llms-full.txt for assistants that read a whole corpus at once. A source that is a PDF works too: convert a PDF to Markdown with the free tool, or let a crawl follow the PDFs a site links to.
Search returns fresh pages as Markdown for a retrieval step, and the agent answers a question with the pages it used.
Retrieval-augmented generation lets a model answer from your own documents. The pipeline collects those documents, splits and embeds them, and stores them in a vector database for retrieval. MeshArc handles collection and freshness for web sources.
llms.txt is a plain-text file at a site’s root that gives AI assistants a clean map of what the site contains. MeshArc generates llms.txt and llms-full.txt from any crawl.
24 Oct 2026 · 8 min read
Re-embed what changed. Leave the rest alone.